Abhi develops statistical and machine learning methods for large spatial datasets as well as Bayesian models for multi-source epidemiological datasets.
JHU BLAST Working Group
Bayesian Learning and Spatio-Temporal modeling
Department of Biostatistics
Johns Hopkins Bloomberg School of Public Health
Leadership
Aki uses Bayesian methods and statistical computing to tackle methodological challenges in healthcare analytics and large-scale biomedical applications.
Upcoming Events
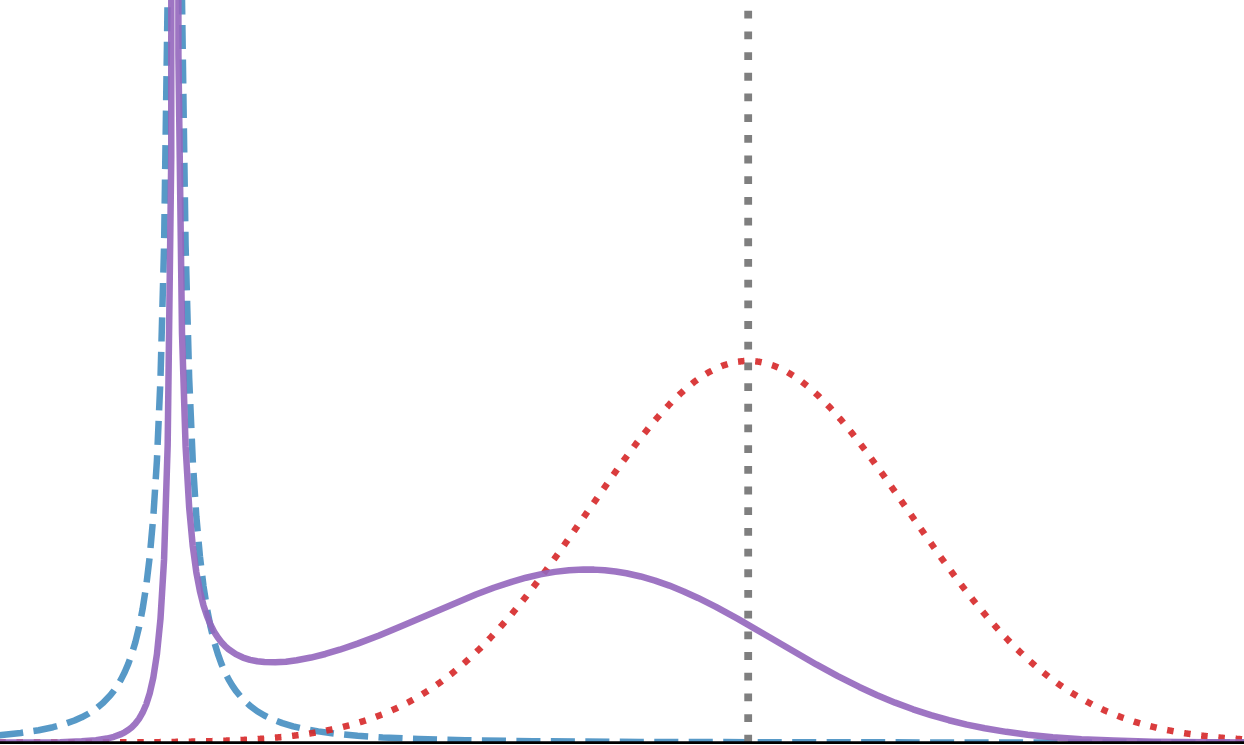
Bayesian high-dimensional regression is a powerful statistical tool, but the complexity and scale of modern data pose a range of challenges in its real-world applications. In this talk, I will present theoretical, methodological, and computational developments to meet these challenges, with particular focus on applications to genetic and electronic health records data. I start with a discussion of a critical yet previously overlooked issue in a widely used statistical paradigm for constructing genetic risk scores: when combining summary-level data with external reference data, a mismatch between the two data sources can cause the posterior to become improper. I provide a precise characterization of the root cause and propose a statistically principled resolution of the mismatch issue. I next turn to the question of how to scale sparse regression models to modern datasets, focusing on posterior computation under global-local shrinkage priors. Among other challenges, I will address a key computational bottleneck that has previously received insufficient attention: pathologically slow mixing in the global scale parameter. Then, motivated by the problem of transfer learning in a high-dimensional space, I proceed to present a skewed generalization of the shrinkage prior that simultaneously incorporates prior information and sparsity structure. Finally, I briefly consider an alternative approach to sparse regression based on spike-and-slab priors. I will describe novel “sticky/reversible jump” dynamical Monte Carlo algorithms that, in particular, further the recently discovered connection between Hamiltonian Monte Carlo and piecewise deterministic Markov process samplers.